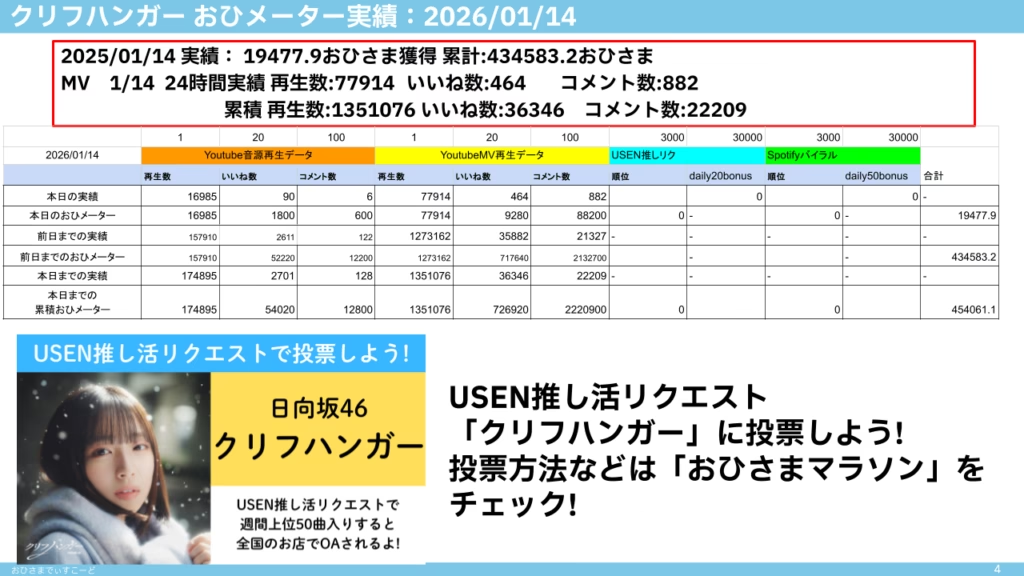
| 2026/01/14 | Youtube音源再生データ | YoutubeMV再生データ | USEN推しリク | Spotifyバイラル | 合計 | ||||||
| 再生数 | いいね数 | コメント数 | 再生数 | いいね数 | コメント数 | 順位 | daily20bonus | 順位 | daily50bonus | ||
| 本日の実績 | 16985 | 90 | 6 | 77914 | 464 | 882 | 0 | 0 | – | ||
| 本日のおひメーター | 16985 | 1800 | 600 | 77914 | 9280 | 88200 | 0 | – | 0 | – | 19477.9 |
| 前日までの実績 | 157910 | 2611 | 122 | 1273162 | 35882 | 21327 | – | – | – | – | – |
| 前日までのおひメーター | 157910 | 52220 | 12200 | 1273162 | 717640 | 2132700 | – | – | 434583.2 | ||
| 本日までの実績 | 174895 | 2701 | 128 | 1351076 | 36346 | 22209 | – | – | – | – | – |
| 本日までの 累積おひメーター | 174895 | 54020 | 12800 | 1351076 | 726920 | 2220900 | 0 | 0 | 454061.1 | ||
データコラム連載
Youtubeコメントを分析する。
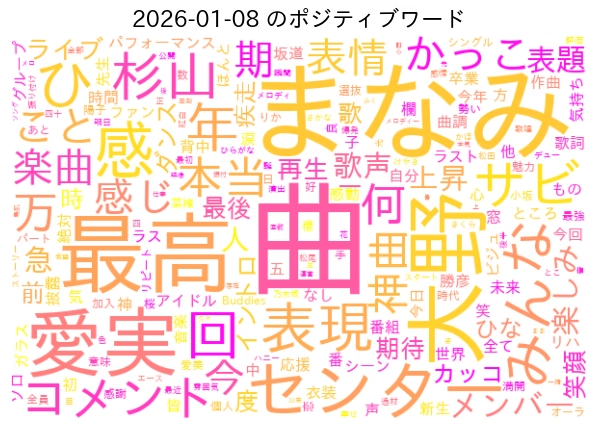
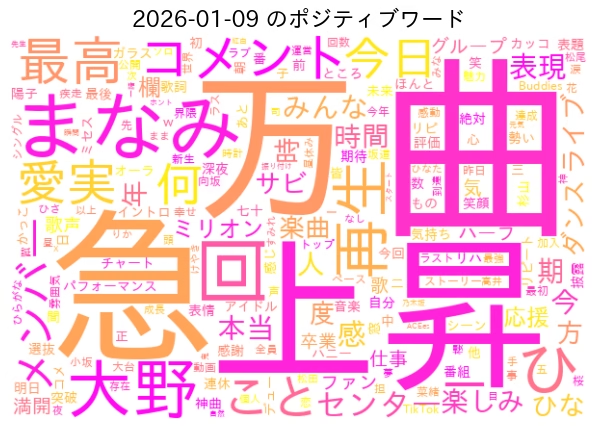
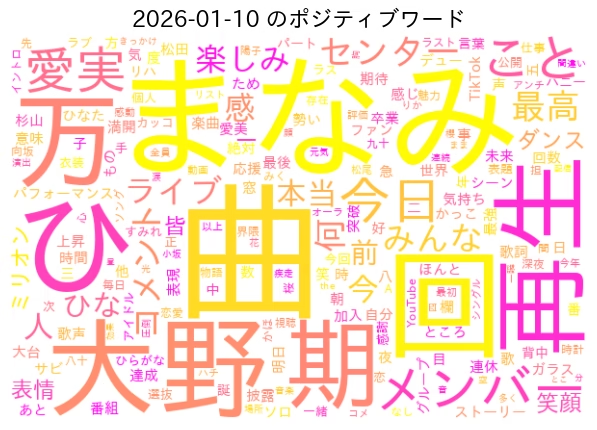
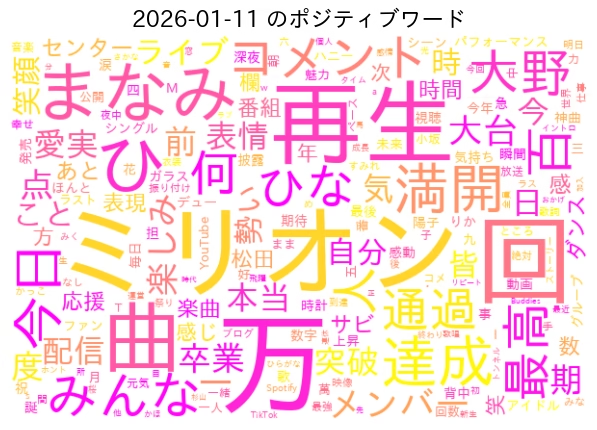
おひさまでぃすこーどでは今シングル向けの新たな取り組みとして「Youtubeコメント」の分析から おひさまがどんなことに興味を持っているのかを分析中です。
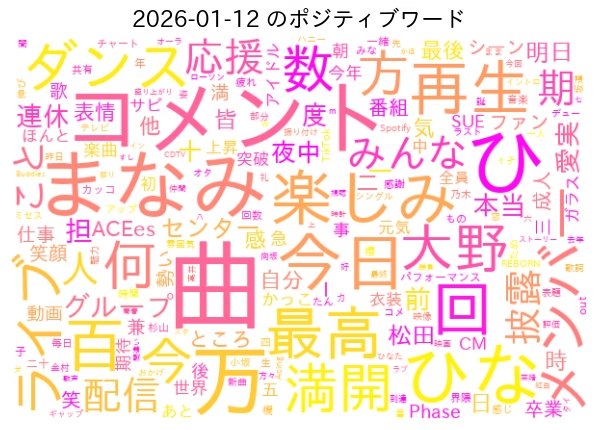
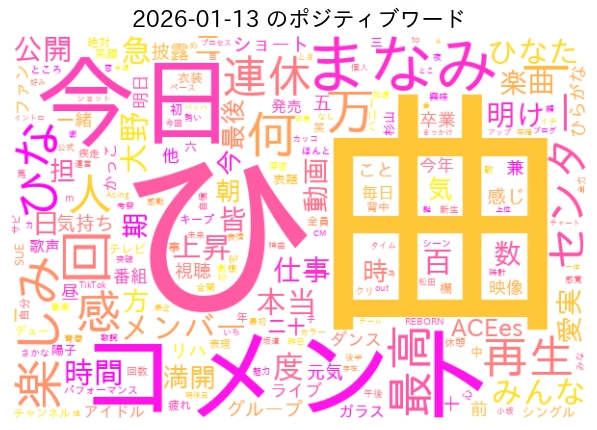
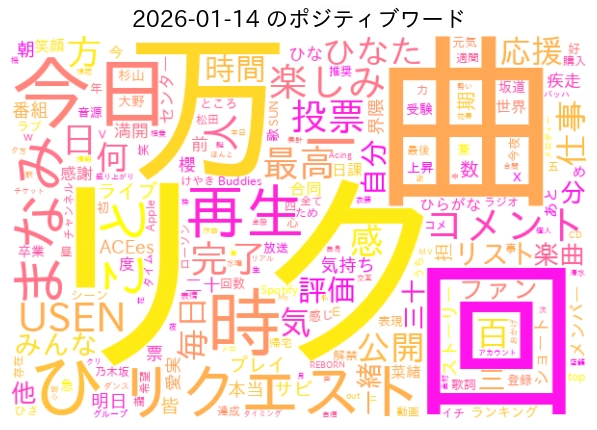
親コメント約1.8万件のコメントデータをもとにGoogleのColaboを活用し、ワードクラウドを作成し、どんなことに興味を持ったのかを探りました。
作成したワードクラウドを時系列でみると 楽曲やMVでのパフォーマンスについて→急上昇入りやミリオン入り等の「実績」について→USEN推しリク等日向坂を応援に向けた話について等変化が見られます。
※コード作成はGoogle Geminiを活用してます。
※日向坂 クリフハンガー等 一部ワードをノイズとして外してます。
!pip install transformers fugashi ipadic unidic-lite japanize-matplotlib tqdm wordcloudimport pandas as pd
from google.colab import auth
from google.auth import default
import gspread
from transformers import pipeline
import torch
import matplotlib.pyplot as plt
import japanize_matplotlib
from tqdm import tqdm
from wordcloud import WordCloud
import fugashi
import os
# --- 設定 ---
SHEET_URL = 'コメントを取得したGoogleスプレッドシートのURL'
TARGET_COLUMN = 'コメント内容'
DATE_COLUMN = '投稿日(JST)'
# ★ここで除外したい単語を設定します
EXCLUDE_WORDS = {'日向坂', '日向', 'クリフハンガー', 'クリフ', 'ハンガー', 'MV', '坂'}
# ------------
# 1. Google認証 & データ読み込み
print("Google認証とデータ読み込みを行います...")
auth.authenticate_user()
creds, _ = default()
gc = gspread.authorize(creds)
workbook = gc.open_by_url(SHEET_URL)
worksheet = workbook.sheet1
rows = worksheet.get_all_values()
df = pd.DataFrame(rows[1:], columns=rows[0])
# 2. 日付データの変換
print("日付データを処理しています...")
try:
df['datetime'] = pd.to_datetime(df[DATE_COLUMN], errors='coerce')
df['date_str'] = df['datetime'].dt.strftime('%Y-%m-%d')
except:
pass
# 3. 分析モデル準備
device = 0 if torch.cuda.is_available() else -1
print(f"分析モデルをロード中... (モード: {'GPU' if device==0 else 'CPU'})")
sentiment_analyzer = pipeline(
"sentiment-analysis",
model="koheiduck/bert-japanese-finetuned-sentiment",
tokenizer="koheiduck/bert-japanese-finetuned-sentiment",
device=device
)
# 4. 分析実行
def analyze_sentiment(text):
if not text: return None
try:
return sentiment_analyzer(str(text)[:512])[0]
except:
return None
print("全データの感情分析を開始します...")
tqdm.pandas()
results = df[TARGET_COLUMN].progress_apply(analyze_sentiment)
df['感情判定'] = results.apply(lambda x: x['label'] if x else None)
print("分析完了!")
# --- 日別ワードクラウド生成(除外設定付き) ---
print("\nポジティブコメントの日別ワードクラウドを作成します...")
tagger = fugashi.Tagger()
def extract_nouns(text):
if not isinstance(text, str): return ""
words = []
for word in tagger(text):
if word.feature.pos1 == '名詞' and word.feature.pos2 not in ['非自立', '代名詞', '数']:
words.append(word.surface)
return ' '.join(words)
font_path = os.path.join(os.path.dirname(japanize_matplotlib.__file__), 'fonts', 'ipaexg.ttf')
# ★設定にstopwords(除外リスト)を追加しました
wc_config = {
'font_path': font_path,
'width': 600, 'height': 400,
'background_color': 'white',
'regexp': r"[\w']+",
'colormap': 'spring',
'collocations': False,
'stopwords': EXCLUDE_WORDS # ← ここで除外リストを適用
}
positive_df = df[df['感情判定'] == 'POSITIVE'].copy()
grouped = positive_df.groupby('date_str')
target_dates = sorted(positive_df['date_str'].dropna().unique())
if target_dates:
MAX_DAYS = 20
if len(target_dates) > MAX_DAYS:
print(f"※日数が多いため、コメント数が多い上位 {MAX_DAYS} 日分を表示します。")
top_dates = positive_df['date_str'].value_counts().nlargest(MAX_DAYS).index
target_dates = sorted(top_dates)
for date in target_dates:
day_comments = grouped.get_group(date)[TARGET_COLUMN]
full_text = " ".join(day_comments.astype(str))
nouns = extract_nouns(full_text)
# 除外後の単語数が少ない場合はスキップする処理
# (WordCloud内部でも除外されますが、念のため生成前にチェック)
if len(nouns) < 10: continue
wc = WordCloud(**wc_config).generate(nouns)
plt.figure(figsize=(8, 5))
plt.imshow(wc, interpolation='bilinear')
plt.title(f'{date} のポジティブワード', fontsize=16)
plt.axis('off')
plt.show()
print("全処理が完了しました。")